Telco edge
6 articles
 Edge AI
Agentic Harnesses on Small Devices: Orchestrating From the Edge
Most of an agent's work is orchestration, not large-model inference. Why the harness belongs on small hardware near the data, what runs on a Tenzro edge node today, and what edge harness hosting will add once it ships.
5 min read Computer vision
Computer Vision at the Edge: Infer Locally, Escalate Rarely
Cameras produce far more pixels than anyone should ship to a data centre. A tiered architecture for vision AI: small detectors at the camera or gateway, larger models only for the frames that need them, and privacy built into the split.
4 min read Networking
 for Distributed Inference: Gossip, Re-announcement and Load
A network of machines behind home routers, carrier NAT and corporate proxies still has to deliver every transaction and every heartbeat. How Tenzro's transport, gossip budgets and re-announcement keep messages from getting lost under load.
5 min read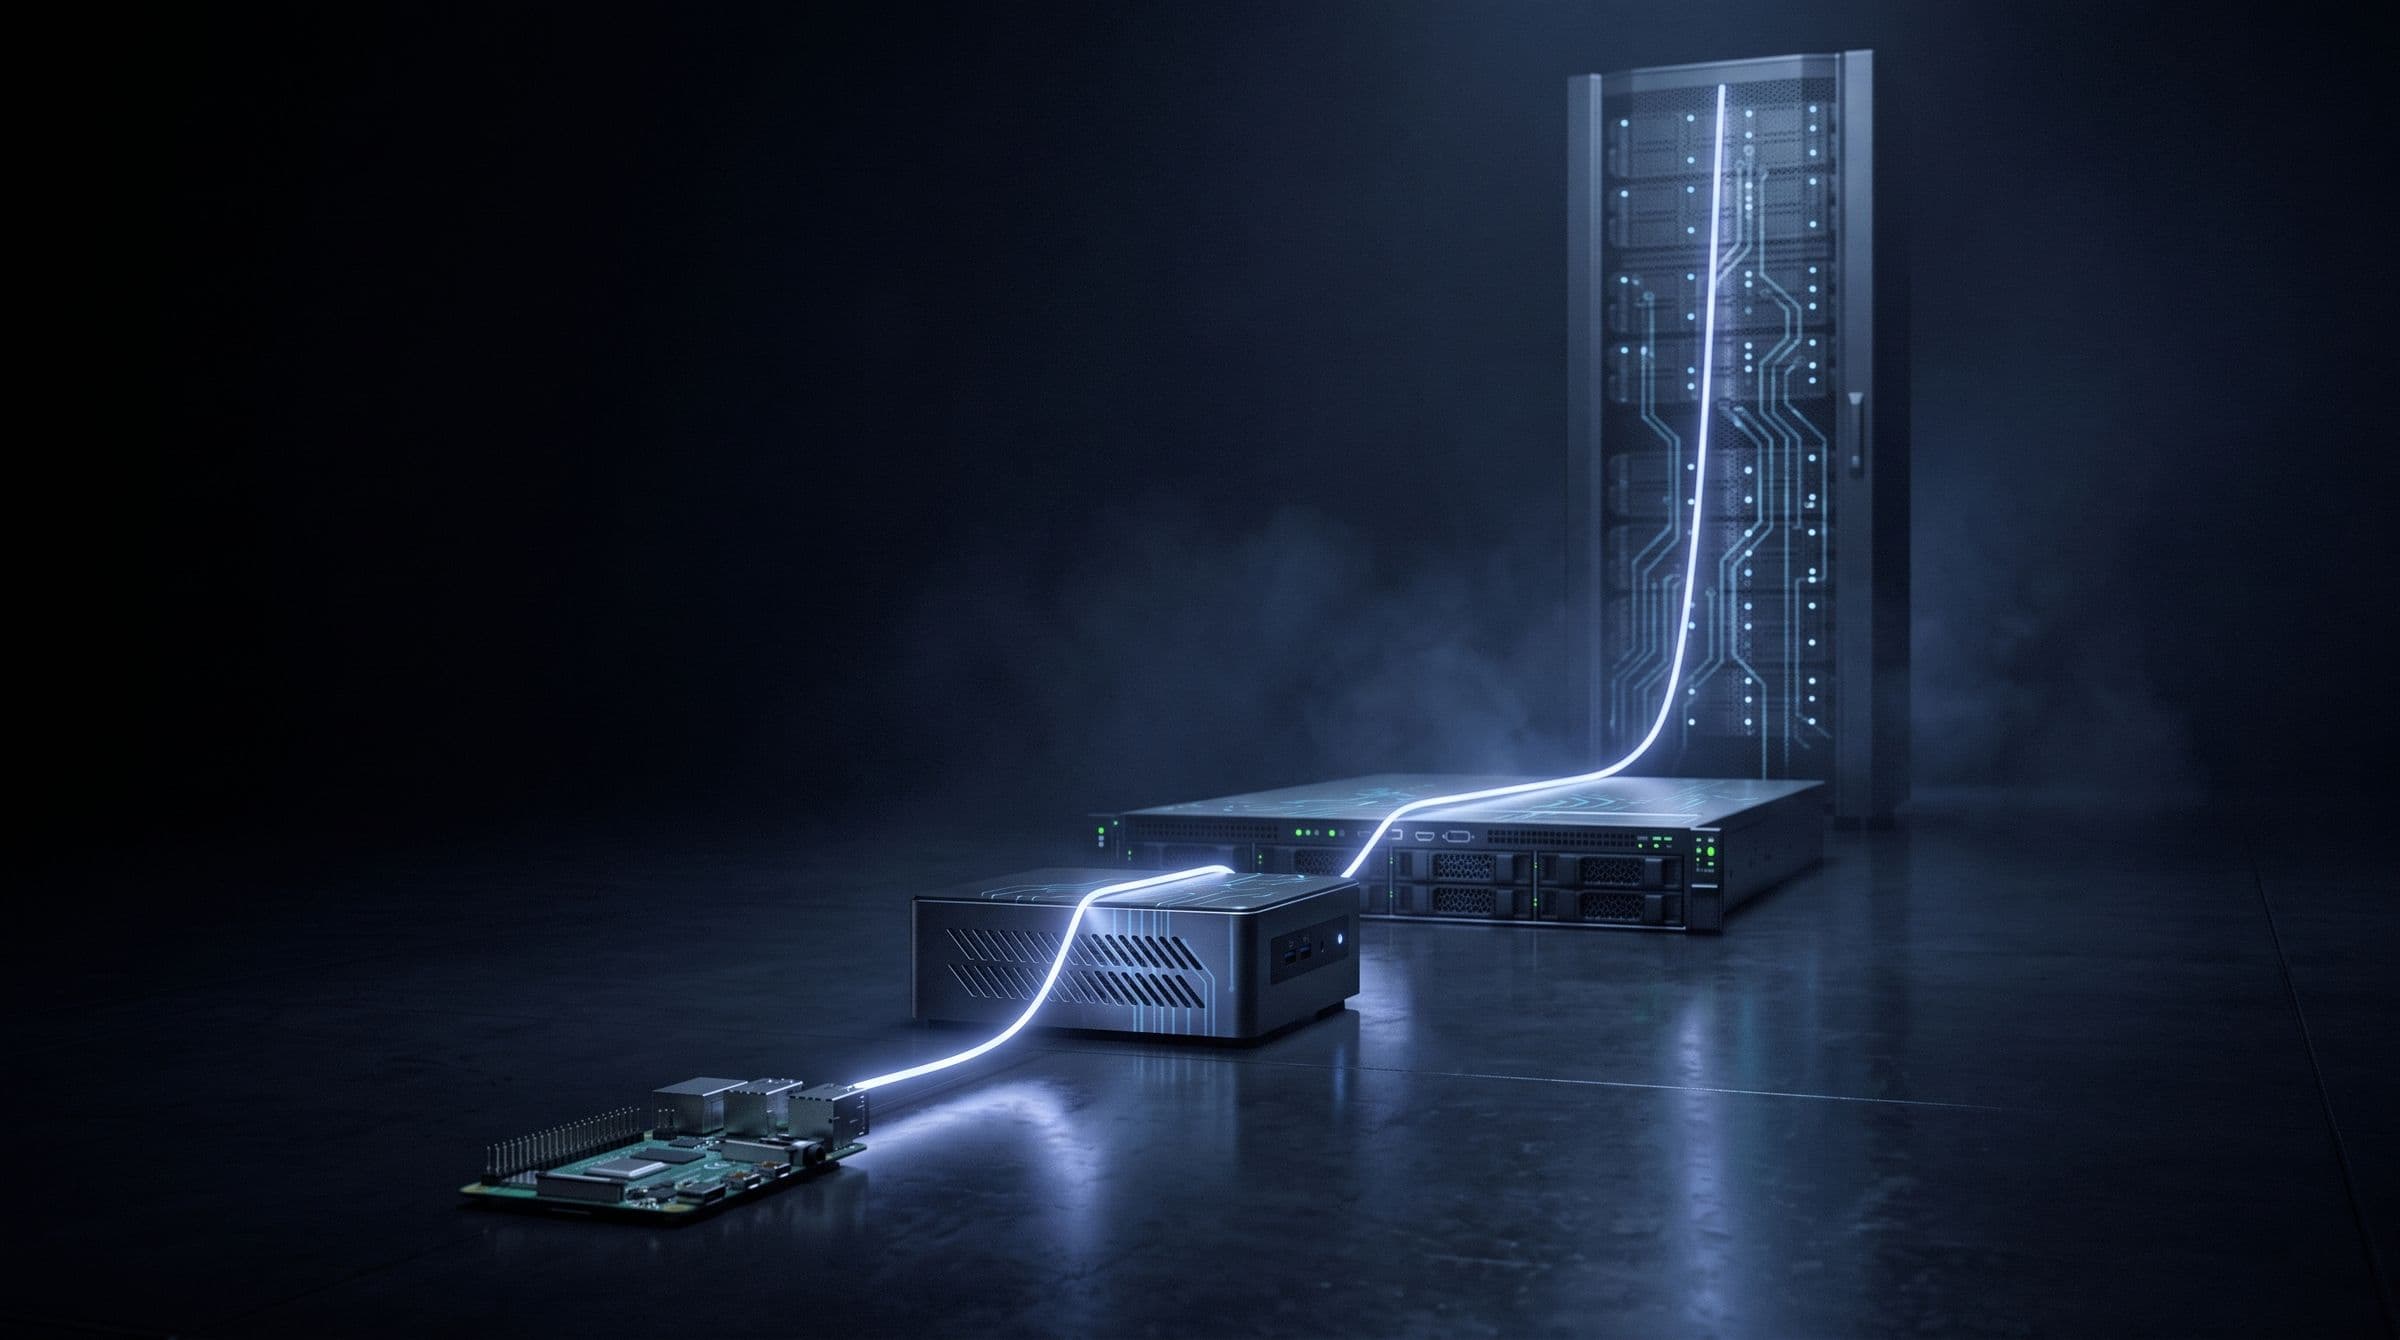 Edge AI
One Codebase From a Single-Board Computer to a Rack
Tenzro builds one node for every class of machine, from a Raspberry Pi to a GPU server, by varying compiled features and resource presets rather than forking the code. How the tiers work, what we measured, and why small devices belong in an AI network.
5 min read Telco edge
Telcos as AI edge clouds: inference inside the latency budget
Telecom operators have the sites, the fibre, the licences and the customer relationships that low-latency AI needs. This article covers how to split an inference request across device, edge and regional GPU, what a latency budget actually allows, and what a telco needs in order to sell edge inference to buyers it has never met.
5 min read Voice AI
 Latency Budgets: Serve Speech Close to the Speaker
People expect a reply within a few hundred milliseconds. A latency budget for voice agents, where each millisecond goes, and why speech recognition and synthesis belong near the user while the language model can sit further away.
4 min read